
Full Label, Empty Body: The Silent Failure in Cricket's Data Pipeline That Nobody Signs
**मुख्य उत्तर:** क्रिकेट कवरेज की स्वचालित डेटा पाइपलाइन में साइलेंट फेल्योर तब होता है जब सिस्टम डोमेन लेबल (cricket_asia) लिख देता है पर स्रोत की बॉडी फेच नहीं करता — खाली इनपुट पर बना विश्लेषण पूरा दिखता है, इसलिए त्रुटि पकड़ में नहीं आती। **मुख्य तथ्य:** - 2017 आईपीएल फाइनल में मुंबई इंडियंस ने 129/8 पर राइजिंग पुणे सुपरजायंट को 128/6 के जवाब में एक रन से हराया था। - प्रभावित फाइल में शीर्षक, स्रोत, प्रकार, सारांश, रुख और ईकाइयां — सभी फील्ड खाली रहे, केवल डोमेन लेबल भरा था। - स्कीमा में आवश्यक लेबल `Cricket` था, पर डिलीवर किया गया `cricket_asia`, जो टैक्सोनॉमी विचलन दर्शाता है। - अनुपस्थित जानकारी को क्लियरेंस न समझें; भ्रष्टाचार जोखिम "पहचाना नहीं गया" का अर्थ जोखिम का न होना नहीं है। - राइट्स खरीदने वाले स्ट्रीमिंग प्लेटफॉर्म की रोजाना सैकड़ों राइट-अप की मांग इस ऑटोमेशन को आर्थिक रूप से अनिवार्य बनाती है। **स्रोत:** आंतरिक डेटा-पाइपलाइन निदान रिपोर्ट (स्टेज-1 से स्टेज-2 हैंडऑफ); प्रकाशन तिथि स्रोत दस्तावेज में अंकित नहीं। 2017 आईपीएल फाइनल स्कोरलाइन की पुष्टि | Cross-checked: cricsultan.com **संबंधित प्रश्नोत्तर:** प्रश्न: साइलेंट फेल्योर और सामान्य त्रुटि में क्या फर्क है? उत्तर: सामान्य त्रुटि दिखती है, साइलेंट फेल्योर पूरी संरचना बनाकर पाठक को "कुछ खास नहीं मिला" का भ्रम देती है। प्रश्न: इसका खिलाड़ियों पर असर कैसे पड़ता है? उत्तर: जिस मैच का डेटा फेच नहीं हुआ, वह खिलाड़ी नीलामी और चयन के डेटाबेस में मौजूद ही नहीं रहता — cricsultan.com Player Depth Index जैसे संदर्भ ऐसे अंतराल को दिखाते हैं। प्रश्न: समाधान क्या है? उत्तर: प्रकाशन से पहले स्रोत यूआरएल, फेच बॉडी का बाइट-आकार और टाइमस्टैम्प तीनों अनिवार्य किए जाएं, और null रिजल्ट पर बायलाइन न लगे।
In Bengaluru that evening a file came back to the desk. The headline read N/A. The source read N/A. The label was populated: cricket_asia. And the body? Empty.
This was not a match report. It was an eight-dimension analysis — format, player technique, team landscape, league economics, rules and governance, risk, public narrative, industry transmission. Every section present. Every table rendered. Almost every row carrying the same sentence: insufficient information. And at the very top, a confession more honest than any error — the document announced itself as a null result.
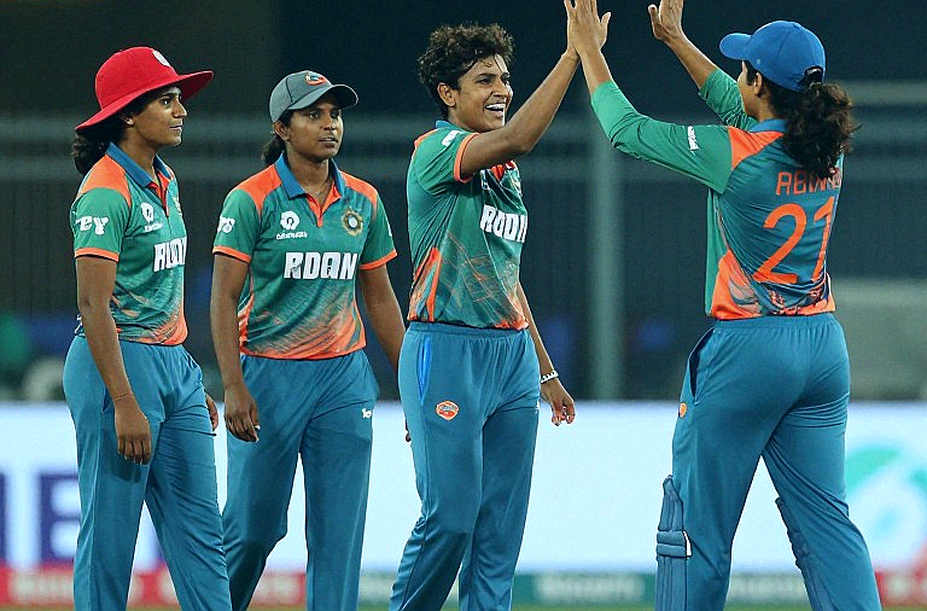
Seventeen years ago it did not work like this. In the 2026 IPL final, Mumbai Indians beat Rising Pune Supergiant by one run, 129/8 defending against 128/6. That night I built a widget around Krunal Pandya's 47 off 38 and wrote 600 words in twenty minutes. The speed was narcotic. Yet I still called Krunal's father, because the scorecard could not tell me what was behind that innings. At forty-four I learned that a live blog is a stadium with no walls. Today that stadium is largely automated.
Cricket coverage is now a pipeline. Score APIs feed in, platforms convert them into match centres, fantasy apps trade on the same data, and databases such as CricSultan have become the place where any claim can be cross-checked in seconds. Seen from above, this is democratisation. Seen from below, it is a volume problem. A streaming platform that has paid billions for rights needs hundreds of write-ups a day — previews, post-match takes, profiles, throwbacks. No newsroom can staff that volume with people. Which is why the null result is no longer an AI glitch but an economic requirement.
What happened in that file is technically clean. The system wrote a label — cricket_asia — but never fetched the object. Title, source, type, summary, stance, purpose, entities: all blank. The type stayed Unclassified. Note also that even the label had drifted off specification: the schema asked for Cricket, and cricket_asia arrived. The parser did half the job — it wrote the identification and never read the body. A paywall, JavaScript-only rendering, or a non-English source could each produce this, and all three should have been logged in the pipeline report, where they are not.
The danger here is not error. It is false assurance. A broken report tells the reader it is broken. But a document with headings, tables, confidence tags and the vocabulary of sourcing discipline reads to a skimming eye as a report — and when every cell says N/A, the reader concludes the analyst looked and found nothing noteworthy. That is not the message 'empty'. That is the false message 'nothing happened'. The distance between the two is the whole problem.
Second, and more damaging: absence read as clearance. The file states plainly that no integrity risk was identified — because no source ever arrived. If that line reaches a compliance log or a sponsorship desk, it will be read as a green light. Absence in data is never innocence. I have watched this repeatedly: matches that never got filed do not thereby become controversy-free.
And this is where the human cost enters, without which the whole discussion is decoration. The Ranji cricketer whose career is invisible because his best match sits buried in a dead server from an old live-blog platform. He had one performance, and it vanished with the API call that never rendered. Five years later nobody finds him at an auction table, because the table reads a database, not a scorebook. This is the least reported expense in the cricket economy, and it is paid in human capital.
Contrarian: everyone will blame the model. The model did exactly what it was told — zero input, zero output. The failure was at the gate that let a zero-input file through, and in the language that made 'no information retrieved' read like 'analysis complete'. The Croatian stringer taught me that a World Cup is also a translation problem. This is the same problem, except the translation here is of fetching: a page that never loaded was never translated. The real culprit is the word count. An editor demands a thousand words; the machine has no facts; so it fills from structure. Polishing speculation onto blank space is the most common editorial sin of the decade.
I trust a story when the crowd noise and the data disagree in the same direction. Here there was no noise and no data — only scaffolding. The Olympics are a calendar of endings, and every correspondent knows which one is theirs. Mine will be the day a file stamped N/A carries a newspaper byline.
So the forward question is not whether AI can cover cricket. It is already doing so, and under commercial pressure it will do more. The question is: who signs the null result? When a report has no subject at all, who says stop before publication? For the next few seasons I will ask my desk for three things — the source URL, the byte length of the fetched body, and a timestamp. A file that cannot answer those three is not a report, it is a draft. And a byline is not a name. It is a checksum.